Generative AI and Language Models
Learning Objectives
- You know the term generative AI and understand what sorts of tasks generative AI models can perform.
- You understand that the outputs of generative AI models are influenced by the training data and the inputs given to the model.
- You are aware of different model families used in generative AI (GANs, diffusion models, transformers).
- You understand both the opportunities and risks associated with generative AI.
What is generative AI?
Generative AI represents a branch of artificial intelligence focused on creating new content rather than analyzing or classifying existing content. While traditional AI systems might identify whether an image contains a cat, detect faces in photographs, or predict tomorrow’s weather based on atmospheric data, generative AI produces entirely new outputs — images, text, music, video, and other forms of content.
The fundamental approach involves training models on large datasets to learn underlying patterns, structures, and styles. The goal is not simply to memorize and replicate training examples but to internalize general patterns that enable creation of novel outputs following learned structures. A model trained on millions of artworks can generate new paintings that combine elements from various styles — perhaps merging impressionist techniques with contemporary subjects in ways not present in any training example. A model trained on text corpora can write essays, poems, or functional computer code that didn’t exist previously but follows learned patterns of language structure and content organization.
Understanding generative AI requires recognizing that its outputs always reflect two key influences: the data it was trained on (which provides the patterns and knowledge it has learned) and the inputs or instructions it receives from users (which guide what specific content it generates). A model trained primarily on English-language scientific papers will generate very different outputs than one trained on creative fiction, even given identical prompts.
Definition of generative AI
0 / 5 points
Which of the following statements correctly describe generative AI? (Choose all applicable)
Model architectures and families
Generative AI builds on decades of machine learning and neural network research discussed in the previous chapter. Several influential architectures have driven recent progress, each with distinct approaches to generating content.
Variational Autoencoders (VAEs, 2013) learn compressed representations of data that capture essential features while discarding less important details. The architecture consists of an encoder that compresses input data into a lower-dimensional latent space and a decoder that reconstructs outputs from these compressed representations. By learning meaningful compressed representations, VAEs can generate new examples that resemble training data but aren’t simply copies. They work by encoding input into a probability distribution rather than fixed values, allowing sampling of variations from this learned distribution.
Generative Adversarial Networks (GANs, 2014) employ an adversarial training process involving two neural networks in competition. A generator network creates synthetic content while a discriminator network attempts to distinguish real training examples from generated fakes. Through this competitive dynamic, the generator becomes increasingly skilled at producing realistic outputs that fool the discriminator.
Transformers (2017-present) introduced in the paper “Attention Is All You Need” by researchers at Google, revolutionized how models process sequential data. The key innovation is the attention mechanism, which allows models to weigh the relative importance of different parts of input when generating each element of output. Rather than processing sequences strictly left-to-right, they can attend across the entire input sequence within the model’s context window. This enables capturing long-range dependencies and complex relationships in data. Transformers underpin many state-of-the-art large language models.
Diffusion Models (2020s) generate content through an iterative refinement process. They work by starting with random noise and gradually “denoising” it into coherent outputs through many small steps. The model learns to predict how to remove noise at each step, eventually transforming pure randomness into structured content matching desired characteristics. Diffusion models power popular image generation tools like Stable Diffusion and DALL·E, which generate detailed images from text descriptions. They often produce higher-quality results than GANs while being more stable to train.
All these models build on decades of research in neural networks, optimization algorithms, and training techniques. Advances in computational power (especially GPUs), availability of large datasets, and improved training methods have enabled scaling these to unprecedented capabilities.
Examples of generative AI outputs
To illustrate generative AI capabilities concretely, Figure 1 shows an image created by ChatGPT from the prompt “Please create an image that represents the Finnish school system in the year 1970.”. The image was created in 2024.
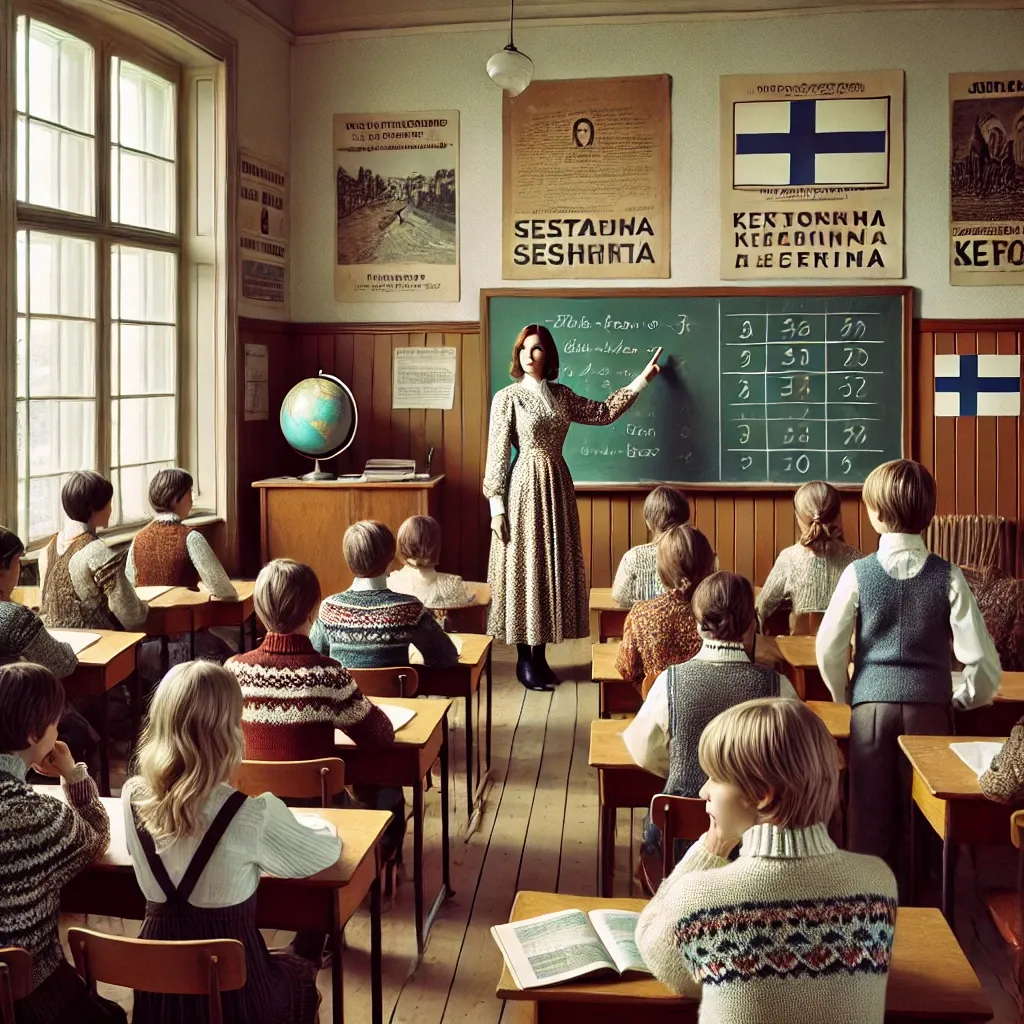
Image generation normally synthesizes an image from learned patterns rather than retrieving a photograph. Here, the wooden desks, clothing, and classroom setting create an impression of the requested period, but the result is not a historical record. Synthesis also does not guarantee originality: researchers have shown that diffusion models can sometimes reproduce memorized training images. We cannot establish from this illustration alone whether any details reproduce training data.
Prompts can also modify existing content. Figure 2 shows the same classroom image modified with the instruction “Please add an elephant to the classroom.”
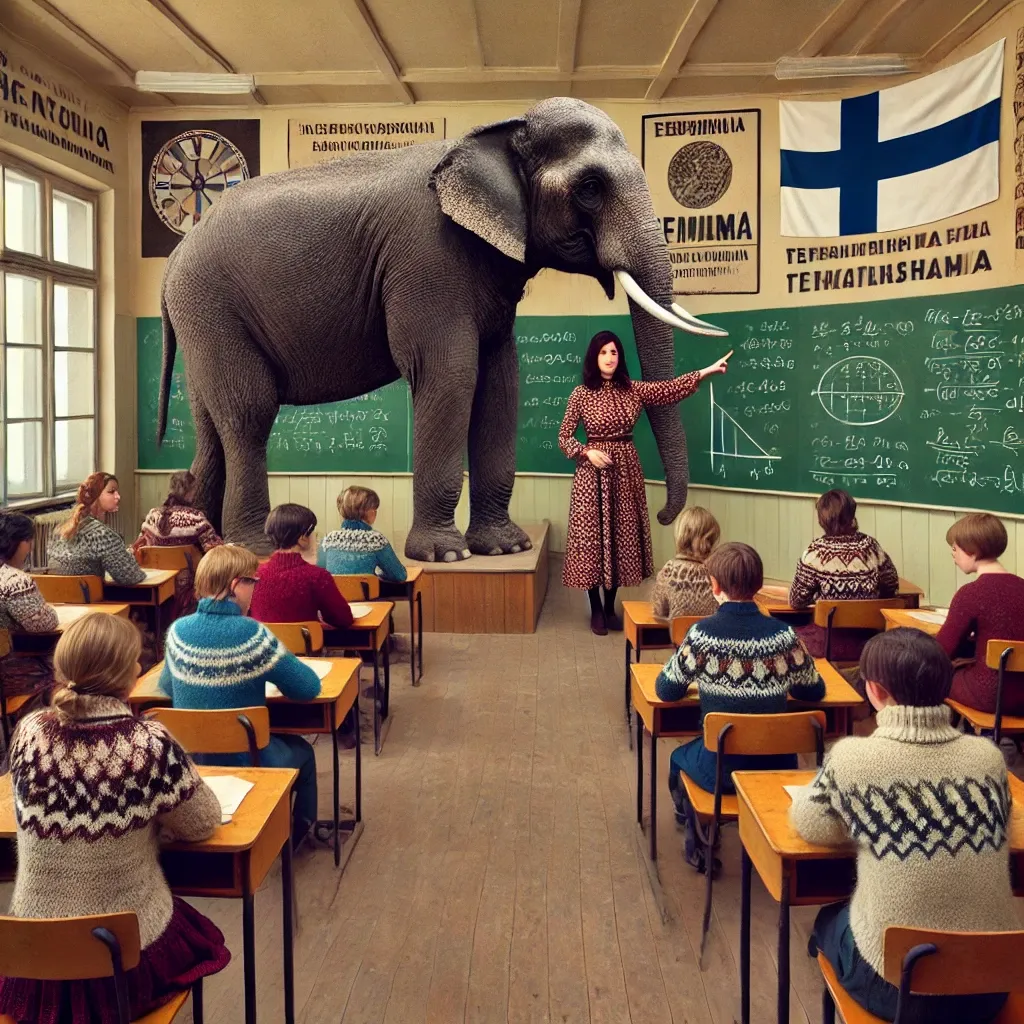
The model integrates the elephant into the scene, while also adjusting other parts of the image to maintain visual coherence. This demonstrates how generative models can modify and extend existing content while maintaining visual coherence.
However, generative AI will attempt to follow prompts regardless of whether they make factual sense. Figure 3 shows a response to the deliberately absurd request for “a CPU invented in 1700 by Aztecs from the Byzantine Empire.”
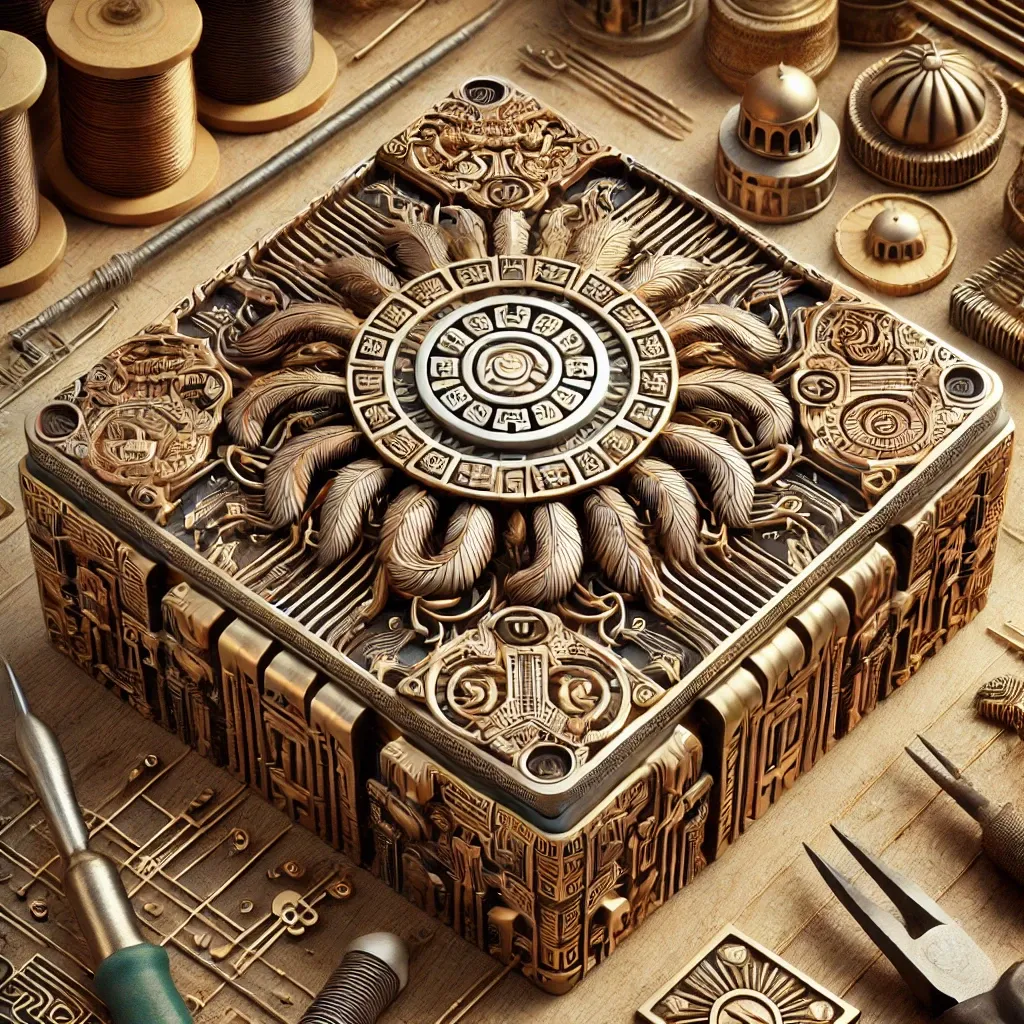
This reveals a critical limitation: a plausible-looking generated image is not evidence of factual accuracy. Central processing units did not exist in 1700. The Aztec Empire was in Mesoamerica, while the Byzantine Empire was centred in the eastern Mediterranean; neither empire still existed in 1700. Their histories did overlap: the Aztec Empire dates from 1428 to 1521, while Byzantium lasted until 1453. The image combines visual motifs that match the prompt without resolving these historical contradictions.
This limitation applies equally to text generation. Language models produce fluent, authoritative-sounding text even when describing events that never occurred, citing nonexistent sources, or making logically impossible claims. The appearance of confidence or plausibility does not indicate factual accuracy.
Characteristics of generative AI outputs
0 / 5 points
Which of the following is true about the outputs generated by generative AI models?
Large language models
Large language models (LLMs) represent a major application of generative AI focused on text. These models are trained on enormous text corpora — often hundreds of billions or even trillions of words drawn from books, websites, scientific papers, code repositories, and other sources. Through this training, they learn statistical patterns and relationships between words, phrases, and longer textual structures.
This learning enables LLMs to generate coherent text for diverse purposes: writing essays or articles, producing computer code, summarizing documents, translating between languages, answering questions, or engaging in extended conversations. The quality and coherence of generated text has improved dramatically in recent years as models have grown larger and training methods have been refined.
The foundation of modern LLMs is the transformer architecture introduced in 2017. The key innovation is the attention mechanism, which allows models to dynamically focus on relevant parts of input when generating each word. In the sentence “The cat, which had been hiding under the porch all morning, finally came out,” a transformer can connect “came out” with “cat” despite the distance between these words, because attention allows the model to recognize their relationship. Earlier architectures like recurrent neural networks struggled with such long-range dependencies.
This breakthrough enabled several influential model families:
GPT (2018-present): The Generative Pre-trained Transformer series developed by OpenAI uses a causal approach, training models to predict the next token from preceding tokens within the context window. Tokens can be words, parts of words, or other pieces of text. This training supports text generation; further training can adapt a model to dialogue. The GPT-4 technical report reports performance across many language tasks but does not disclose the model’s parameter count, so we cannot use it to establish a parameter-count increase over earlier GPT models.
BERT (2018): Developed by Google, BERT (Bidirectional Encoder Representations from Transformers) processes text bidirectionally rather than left-to-right only. It reads entire sequences in both directions simultaneously, making it particularly effective for understanding language in context. BERT is widely used in search engines and classification tasks where comprehension matters more than generation.
Recent multimodal models (2021-present): Modern LLMs increasingly process not only text but also images, audio, video, and other modalities. GPT-4 can analyze images and answer questions about their content. Models like CLIP learn representations connecting text and images, enabling applications that bridge language and vision. These multimodal capabilities represent a significant expansion beyond text-only processing.
Below is an example of ChatGPT generating a concise explanation (the chat examples have been created in 2024):
Please explain generative AI in one paragraph.
Generative AI refers to a subset of artificial intelligence models designed to generate new, original content based on patterns and data they've been trained on. These models can create a wide range of outputs, such as text, images, music, and even videos, by learning from vast datasets and understanding the underlying structures within them. Unlike traditional AI, which focuses on classification or prediction, generative AI is about creating something new, from generating human-like text with models like GPT-4 to creating realistic images with tools like DALL-E. It has numerous applications, including content creation, design, drug discovery, and more, but it also raises ethical questions regarding originality, misuse, and potential biases in the generated content.
Prompts significantly influence not just what content is generated but how it’s presented. The same request with a different specified audience produces very different output:
Summarize generative AI in one paragraph for an audience consisting of kittens.
Generative AI is like a magical friend who can create things from scratch! Imagine if you wanted a new story, a picture of a fish, or even a song about your favorite ball of yarn -- generative AI can make it happen. It learns by looking at lots of different examples, like how you learn by watching your mama cat. Then, it uses that knowledge to come up with new, fun creations, just like how you'd come up with a new way to pounce on a toy. It's like having a super creative buddy who's always ready to play!
The model adapts vocabulary (simpler words), sentence structure (shorter, more direct), conceptual analogies (learning from mama cat), and tone (playful and encouraging) to match the hypothetical audience. This demonstrates how prompts shape both content and presentation style, though the model obviously cannot literally communicate with kittens — this represents imaginative role-playing rather than actual audience adaptation.
Understanding large language models
0 / 5 points
Which of the following statements are true about large language models? (Choose all applicable)
Opportunities and risks
Generative AI creates significant opportunities across many domains while simultaneously raising serious challenges that require careful consideration.
Opportunities
Creative tools and assistance: Artists, writers, musicians, and designers can use generative AI to explore variations on ideas, overcome creative blocks, or rapidly prototype concepts that would take much longer to develop manually. A musician might generate melodic variations as starting points for composition. A graphic designer might create dozens of logo concepts in minutes to explore visual directions. A writer might use AI to draft outlines or generate alternative phrasings. These tools augment rather than replace human creativity, handling routine aspects while humans provide direction, judgment, and refinement.
Scientific research and discovery: Generative models contribute to research that would otherwise take years. They can propose novel molecular structures for drug development, predict protein folding patterns (as demonstrated by AlphaFold), design materials with specific desired properties, or generate hypotheses for experimental testing. In drug discovery, generative models can explore vast chemical spaces to identify promising compounds, potentially accelerating development of new treatments. In materials science, they can suggest configurations with particular physical characteristics.
Productivity and accessibility: LLMs can summarize lengthy documents, extracting key points from reports or papers. They can assist with programming by generating code snippets, explaining existing code, or suggesting bug fixes. They can provide tutoring adapted to individual learning needs, translate between languages, and answer questions across many domains. These capabilities can make knowledge work more efficient and make expertise more accessible to those without specialized training.
Risks and challenges
Bias amplification and stereotypes: Because models learn from human-generated data, they absorb and can amplify biases present in that data. An image generator asked to create “a CEO” might predominantly show men, reflecting historical gender imbalances in executive positions. A language model might associate certain professions with particular ethnic groups, or generate stereotypical descriptions. These biases can perpetuate and reinforce social inequalities. While researchers work to mitigate bias through careful dataset curation and model training adjustments, completely eliminating learned biases remains extremely challenging.
Hallucinations and fabricated information: LLMs frequently produce convincing but completely false information — a phenomenon called “hallucination.” They might describe events that never occurred, cite sources that don’t exist, or state false facts with complete confidence. Because generated text appears fluent and authoritative, users may trust it inappropriately. This makes LLMs unreliable for fact-checking or any situation requiring accuracy without verification. The models don’t “know” when they’re hallucinating; they simply generate plausible-seeming text based on statistical patterns.
Intellectual property and copyright questions: Fundamental legal and ethical questions remain unresolved. If a model is trained on copyrighted works (books, articles, artwork, code), does content it generates infringe those copyrights? Who owns AI-generated content — the user who provided the prompt, the company that created the model, or the creators whose work was used in training? Should creators whose work contributed to training data receive compensation? Courts and legislatures are still working through these issues.
Misinformation and malicious use: Generative AI can be weaponized to create fake news articles indistinguishable from legitimate journalism, deepfake videos convincingly impersonating real people, or coordinated disinformation campaigns operating at scale. The technology dramatically lowers barriers to producing misleading content. This threatens public trust in media, democratic processes, and ability to establish shared factual understanding.
Environmental costs: Training large generative models requires enormous computational resources. The largest models require weeks or months of processing on thousands of specialized GPUs, consuming megawatt-hours of electricity and producing substantial carbon emissions. While exact numbers are debated and vary by model and training approach, the environmental impact is significant. Some estimates suggest training a single large language model produces carbon emissions comparable to several transatlantic flights. Ongoing use for inference adds additional environmental costs. Balancing these impacts against potential benefits represents an important consideration for responsible development.
Opportunities and risks of generative AI
0 / 5 points
Which of the following are risks associated with generative AI? (Choose all applicable)